Rank Content search results by relevance - #5568
Conversation


|
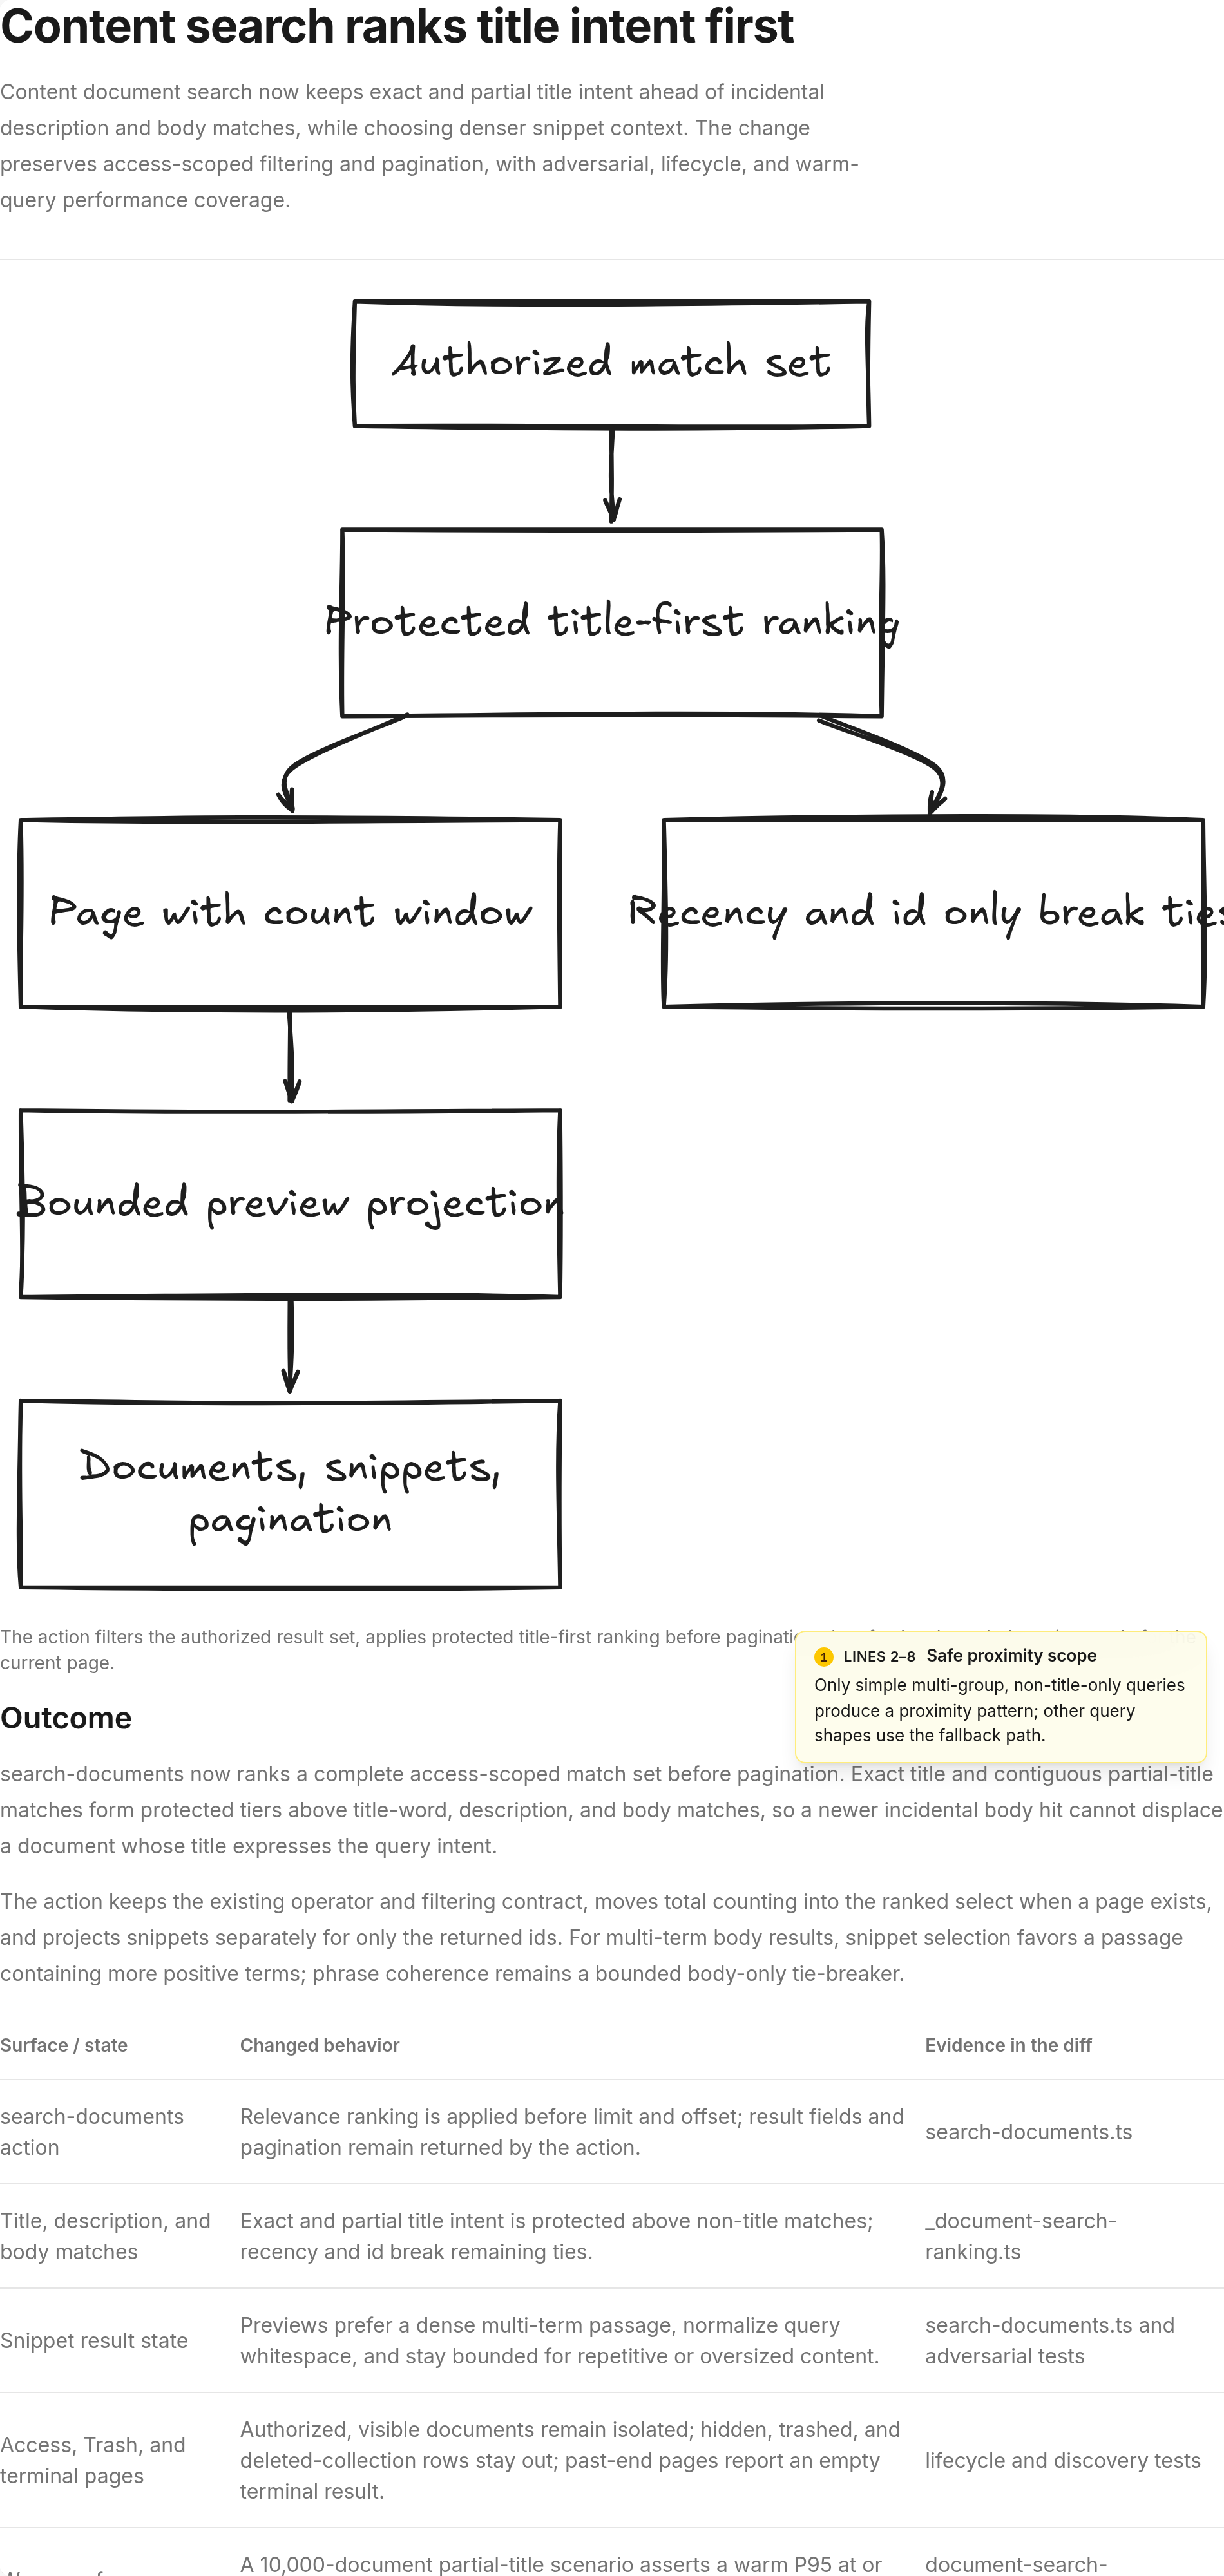
Here's a visual recap of what changed: Open the full interactive recap |

This comment was marked as outdated.
This comment was marked as outdated.
Sorry, something went wrong.

|
Addressed the three review findings in
Focused ranking, discovery, and adversarial suites pass (29 tests), and Content typecheck passes on the updated head.
|
This comment was marked as outdated.
This comment was marked as outdated.
Sorry, something went wrong.
|
Addressed the incremental review findings in
The focused ranking/discovery matrix passes all 31 tests. The standalone 10,000-document fixture passed twice at 264.7 ms and 253.9 ms warm p95 against its 400 ms budget. Content typecheck also passes.
|

There was a problem hiding this comment.
Builder reviewed your changes and found 2 potential issues 🟡
Review Details
Incremental Code Review Summary
The latest commit fixes all four previously open findings: OR alternatives now receive symmetric exact/prefix tiers, title-only searches disable non-title ranking signals, snippet occurrence expansion has a 256-total budget, and quoted snippets normalize whitespace consistently. Those four stale review threads were resolved before this review.
New Findings
- 🟡 MEDIUM — The 10k-document performance contract has regressed again: the ranking query measured approximately 673 ms warm p95 against the asserted 400 ms budget in one independent run. The full authorized set is still evaluated before pagination, so this remains a real request-path latency issue rather than an unused code path.
- 🟡 MEDIUM —
intitle:terms still contribute to description coverage and can reorder results based on a field that the operator explicitly excludes. Title-only operator terms should remain neutral outside title ranking.
The two-query page hydration and access-scoped preview predicate are sound, and the focused functional suites reported by agents passed. Standard risk remains appropriate.
🧪 Browser testing: Could not complete — the browser-test-planner invocation was aborted after the dev server was confirmed healthy, so no visual evidence is available for this incremental review.

There was a problem hiding this comment.
Builder reviewed your changes and has a few items to flag 🟡
Review Details
Incremental Code Review Summary
The latest commit addresses the previously open intitle: ranking leakage: title-only terms are now excluded from description ranking, and that stale thread was resolved. The request-wide snippet occurrence cap and ranking short-circuit changes are directionally sound, and the focused functional suites reported by reviewers pass across ranking, operators, pagination, snippets, lifecycle, and access behavior.
The existing 400 ms warm-search performance comment remains unresolved and was intentionally not reposted. Multiple independent runs still report the 10k-document benchmark above the committed budget, so the PR does not yet satisfy its stated performance target.
No additional confirmed bugs were found in this incremental pass.
🧪 Browser testing: Could not complete — the dev server was healthy, but browser-test executors still have no mcp__chrome__* tools, so the 15-case visual plan could not produce UI evidence.

2 participants


Problem
Content search previously ordered every matching document by modification time. A recent document that mentioned the query incidentally in its body could therefore appear above the document whose title was the intended match. For example, searching
task prioranked an article containing the wordstaskandpriorabove Task Priorities.That behavior made the picker feel arbitrary and forced people to scan through incidental matches even when a strong title match existed.
Approach
Rank the complete authorized result set with protected relevance tiers before applying pagination. Exact titles rank first, followed by contiguous title prefixes, title word-prefix matches, title substring matches, description matches, and body-only matches. Modification time remains the tie-breaker within a tier, so a recent body match cannot overtake a title match.
Body-only results receive a small phrase-coherence signal on result sets of at most 1,000 candidates. Title tier evaluation short-circuits expensive checks for clear body-only matches. Larger result sets retain the protected title and description tiers while skipping that full-body tie-breaker to keep latency predictable. Snippets prefer a passage containing more positive query terms while retaining bounded fallbacks for reverse-order, widely separated, whitespace-normalized, or pathological matches. Search eligibility, access checks, exclusions, filters, and the existing query language remain unchanged.
What changed
limitandoffset, with a window count for ordinary pages and the existing explicit count fallback for offsets past the final page.intitle:terms from influencing description ranking.Safety and operations
This changes read ordering and snippet selection only. It adds no migration, data write, credential, external service, or rollout dependency. The query remains access-scoped before ranking. The main performance risk is evaluating relevance over many eligible rows, so the suite includes mixed-size documents and a 10,000-document warm latency gate.
Verification
task prio, ahead of newer body-only matches; the next page contains the remaining results without duplication.Review focus
count(*) over()plus empty-page fallback correct for all pagination boundaries?